Recommendation-Free Feeds: Curation Over Algorithms
How to build a recommendation-free feed using human curation and simple retrieval instead of engagement-optimizing algorithms — lessons from HackerTube.
 Sarah Chen

It's 11pm on a Friday. You're tired, you open YouTube, and the homepage greets you with a wall of screaming thumbnails, shocked faces, and the same three topics it decided you liked in 2019. Nothing on it is what you want, but you scroll anyway, because scrolling is what the interface is for. If you've ever felt that specific kind of exhaustion, you already understand why recommendation-free feeds are suddenly interesting — and why a YouTube clone built from Hacker News comment recommendations, assembled in about two hours with an AI agent, got so much attention recently.
The project in question is HackerTube: a YouTube-style interface over roughly 6,500 videos that were recommended in Hacker News comments between 2007 and now. No accounts, no tracking, no autoplay manipulations. State lives in your browser's local storage. The whole thing was prompted into existence in a Saturday-morning session, from data extraction to deployment on a VPS. I want to talk about why it works so well, because the lesson generalizes far beyond one fun side project. It works because it has no recommendation algorithm in the conventional sense — and that turns out to be a feature you can deliberately engineer into your own products.
Why Recommendation Algorithms Optimize for the Wrong Thing
I spent a few years working on ranking systems, so let me say the quiet part plainly: the objective function is the product. A platform-scale recommender is trained on engagement proxies — watch time, click-through rate, session length, sometimes dwell time weighted by ad impressions. None of those are "did the user leave satisfied." They're "did the user stay." Those are correlated often enough that you can convince yourself you're building something good, but they diverge in exactly the cases that matter: outrage, titillation, and the twentieth video on a topic you already exhausted.
This is Goodhart's law wearing a trench coat. Once watch time becomes the target, it stops measuring anything about quality. Worse, the feedback loop is closed: the algorithm shapes what gets clicked, the clicks become training data, and the model gets progressively more confident about a progressively narrower picture of you. Several people reacting to HackerTube noted something I've felt myself — the unpersonalized feed of nerd-vetted videos had a higher hit rate than YouTube's deeply personalized one. That shouldn't be surprising. Personalization infers your taste from your weakest moments (what you clicked at 11pm, tired), while curation encodes taste from people's strongest moments (what they bothered to write a comment recommending to peers).
There's a subtler failure mode too: optimized feeds are exquisitely good at showing you more of what you already know. But a lot of why people browse at all is horizon expansion — encountering something surprising that recalibrates your model of the world. Engagement optimization has no gradient signal for surprise-that-pays-off-later. It only knows whether you stayed. This is the same reason I've argued that AI benchmarks miss most of real work: the measurable proxy drifts away from the thing you actually wanted, and the drift compounds.
Human Curation as a Corpus: Mining Hacker News Comments
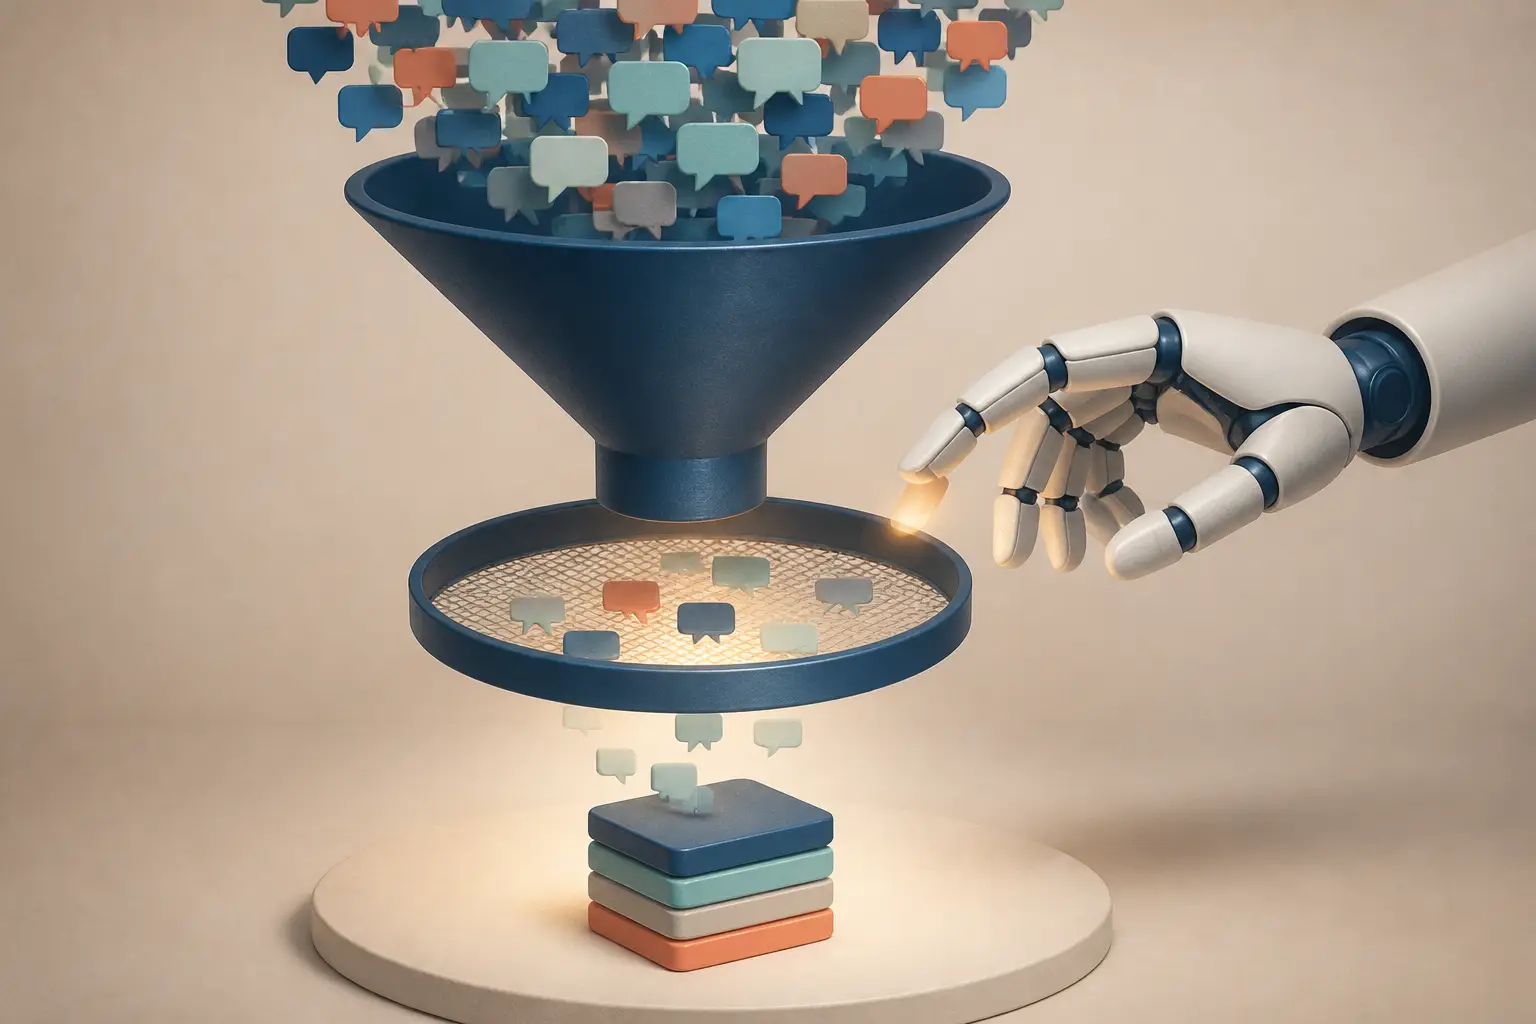
So where does a recommendation-free feed get its inventory? HackerTube's answer is clever because it reuses an existing, high-quality signal: two decades of Hacker News comments. The pipeline is simple to describe. Download all public HN comments (they're available via the official API and community datasets). Filter to comments containing YouTube links — about 40,000 of them. Then run a cheaper LLM pass over each comment to answer one question: is this person actually recommending this video, or is it spam, a drive-by link, or someone citing a video to mock it? That filtering pass narrows the corpus to roughly 6,500 videos across 150 topic clusters.
Two design choices here are worth stealing. First, the classification step is exactly the kind of bounded judgment task LLMs are great at — a yes/no with a short justification, applied at scale for pocket change. It's the same pattern as using constrained decoding to turn LLMs into fast decision models: don't ask the model to generate, ask it to filter. Second, the corpus has a built-in quality floor. Every video in it was vouched for by a human, in writing, in front of an audience that downvotes nonsense. That's a filtering mechanism no engagement model can replicate, because it's anchored in reputation rather than clicks.
A recommendation written in a comment is a person staking their reputation. A click is a reflex. Feeds built on the former feel different because they are different.
There's also a time dimension that matters. These recommendations span 2007 to the present, which means the corpus is dominated by content with staying power — lectures, deep technical talks, long-form interviews — rather than whatever the algorithm is boosting this week. One detail people loved: a "Longs" category for lengthy videos. On YouTube, a 90-minute talk is a risk the recommender takes with your session. On HackerTube, it's a feature, because someone wrote "this changed how I think about compilers" next to it.
Simple Retrieval Beats Smart Ranking
Here's the part that will feel heretical if you've worked in recsys: once your corpus is small and good, ranking barely matters. Six thousand videos is nothing. You don't need a two-tower embedding model and a re-ranking cascade; you need topic tags, recency, and a light personalization pass that runs client-side. HackerTube's "For You" works off session state in local storage — what you've watched and skipped in this browser — with no account and no server-side profile. That is not a limitation. It's an architectural decision that eliminates an entire class of bad incentives: if you don't store user behavior, you can't be tempted to optimize against it.
If you wanted to build your own version of this — a feed of papers, conference talks, blog posts, whatever your community recommends — the ranking logic fits in a few dozen lines. Here's the shape of it:
import math
import time
def score(video, session, now=None):
now = now or time.time()
s = 0.0
# Corpus quality signal: how many distinct humans vouched for it
s += math.log1p(video["recommenders"])
# Gentle recency so the feed isn't frozen in 2014
age_days = max((now - video["recommended_at"]) / 86400, 1)
s += 0.5 / math.log1p(age_days)
# Session-level taste: topics the user finished vs. skipped,
# stored in localStorage — never leaves the browser
for topic in video["topics"]:
s += 1.5 * session["finished"].get(topic, 0)
s -= 1.0 * session["skipped"].get(topic, 0)
# Already watched? Push it down hard, don't hide it
if video["id"] in session["seen"]:
s -= 5.0
return s
def for_you_feed(videos, session, limit=24):
return sorted(videos, key=lambda v: score(v, session), reverse=True)[:limit]
Notice what's absent: no dwell-time feature, no engagement velocity, no exploration-exploitation bandit trying to figure out your breaking point. The personalization signals are explicit (finishes and skips, chosen by the user's own behavior in this session) and bounded (a couple of points each, easily overwhelmed by the corpus-quality term). The algorithm can nudge; it cannot trap. That asymmetry is the entire philosophy in one scoring function.
The thumbnail decision deserves a mention too, because it's such a clean example of de-optimizing an interface. YouTube creators A/B test thumbnails into oblivion, so the thumbnail itself became an adversarial artifact. HackerTube ignores the uploaded thumbnail and uses the frame at the 50% mark of the video instead. It's a one-line change that removes the clickbait arms race entirely — the preview shows you what the video actually is, not what its creator thinks will make you click.
Designing Feeds Without Accounts or Tracking
Moving state to the client changes more than your privacy posture — it changes your cost structure and your legal surface area. No user accounts means no auth system, no password resets, no GDPR subject-access machinery, no breach liability for behavioral profiles. Your backend is a static file server and maybe one tiny API. The whole site can be a build artifact. When your architecture can't accumulate user data, most dark patterns become physically impossible rather than merely policy-violating. I find that kind of guarantee far more trustworthy than any privacy policy.
The honest trade-off: local state is ephemeral and device-bound. Clear your browser data and your feed resets. There's no cross-device continuity. For a lean-back video site, that's fine — I'd argue the reset is occasionally even healthy. For anything where users build long-term collections, you'll want an export/import escape hatch, which conveniently brings us to the most forward-looking decision in the whole project.
Data as the Interface: Shipping a Forkable Corpus
The part of HackerTube I find genuinely novel isn't the UI — it's that the entire dataset behind the site is downloadable as a zip that includes a DATA.md written specifically for AI agents. It documents how the files fit together, the gotchas, example records, and how to fetch fresh metadata. The intended workflow: hand the zip to your coding agent and say "make me a weekly email of talks on my topics" or "build me a terminal client for this." The product isn't the website. The product is the curated corpus, and the website is just the reference renderer.
This is a pattern I think we'll see a lot more of. For two decades, the standard advice was "expose an API." But an API still makes you the gatekeeper of queries, and it rots the moment you stop maintaining it. A portable, agent-legible dataset inverts the relationship: you publish the thing once, well-documented, and let a thousand personalized frontends bloom. It rhymes with the ethos of the small web — discovery built on people linking to things they loved, rather than platforms deciding what you see — updated for a world where the first consumer of your data might be a language model.
Writing documentation for agents is its own emerging craft. Humans skim; agents read literally and completely, and they flounder on implicit assumptions a human would infer. A good DATA.md states units, nullability, encoding quirks, and failure modes up front. If you publish datasets, this is now table stakes — the difference between an agent producing a working fork in one pass and hallucinating a schema.
The Honest Limitations of Curated Feeds
I promised pragmatism over hype, so here are the sharp edges. First: a curated corpus inherits the biases of its curators. Hacker News is a specific demographic with specific taste — the result is "100% pure nerd content," which is delightful if you're the target audience and invisible if you're not. This approach doesn't scale to "everyone," and it doesn't try to. It's a pub, not a utility.
- Staleness: a frozen snapshot decays. You need a scheduled job re-running the extraction pipeline, or the feed quietly becomes a museum.
- Platform dependence: the videos still live on YouTube. Deletions, region locks, and ToS changes will rot your corpus from underneath you. Track dead links or lose trust.
- Demographic lock-in: whoever does the recommending defines the taste. Fine for a community site; a serious bias problem if you ever pitch it as neutral discovery.
- Freshness ceiling: brand-new great content has no recommendations yet. Curated feeds systematically under-serve the new, which is precisely the gap engagement algorithms fill — for better and worse.
That last point is the one that keeps me honest about this whole approach. Engagement feeds and curated feeds aren't enemies; they're optimized for different time horizons. Curation tells you what proved valuable. Engagement ranking, at its best, surfaces what might become valuable. The healthy version of YouTube's recommender would look a lot like HackerTube's corpus with a small, clearly-labeled "new and unproven" lane. The tragedy isn't that recommendation algorithms exist — it's that the business model demands they be the whole interface.
When You Should Build This Yourself
The two-hour build time is the story inside the story. This project wasn't feasible at this speed five years ago — not because any single step is hard, but because there are forty fiddly steps: extraction, filtering, metadata enrichment, UI, deployment, hardening. An agent that can hold the whole plan in context collapses that into a prompting session. That means the barrier to building niche, curated alternatives to platform feeds has dropped to roughly "one motivated person with a Saturday morning."
So here's my take, and I'll commit to it: if you run any product with a feed — an internal knowledge base, a community forum, a content product — you should prototype the curated version before you build the algorithmic one. Start with explicit human recommendations, filter them with a cheap LLM pass, rank with a scoring function simple enough to explain in a standup, and keep state client-side as long as you can. You'll learn whether you actually have an inventory problem or a ranking problem, and in my experience it's almost always inventory. The engagement-optimized feed is a tool for maximizing a metric. The curated feed is a tool for respecting a person. Build the second one first, and only reach for the first when you can articulate exactly why — and for whom — it deserves to exist.


