LLM Conjecture Generation vs Proof-Checking: Who Wins
LLMs now do conjecture generation, not just proof-checking. When each wins in math research, and the verification loop that makes machine proofs safe.
 Elena Vasquez
Somewhere between the second and third coffee, a lot of complexity theorists recently read a sentence they never expected to read: a deterministic algorithm that counts the satisfying assignments of an arbitrary Boolean formula in time roughly 2^(n/√(log n)) — sub-exponential, in the precise technical sense that refutes the Exponential Time Hypothesis, one of the field's load-bearing assumptions. The claim didn't surface on the arXiv from a university group. It came from an AI lab, with the proof developed in collaboration with a large language model. Whatever else you think of the announcement, it marks the moment conjecture generation — machines proposing new mathematics rather than merely grading it — left the demo stage.
The lab bundled three results: the complexity-theoretic bombshell above, a claimed proof of the Kakeya conjecture in all dimensions, and a physics result described as a unified completion of the Standard Model, held back pending formal verification. The reaction split in a familiar pattern: genuine astonishment at the substance, genuine irritation at the packaging. Critics compared it to a bicycle manufacturer announcing its own victories in bicycle racing. Apt — and yet the substance deserves a slower look, because buried in this announcement is a real lesson about the two very different ways language models now touch mathematics, and which of the two you should actually trust.
What the AI Math Announcement Actually Claims
Start with the complexity result, because it has the clearest stakes. The Exponential Time Hypothesis says, roughly, that 3-SAT cannot be solved in 2^o(n) time — no algorithm can be meaningfully sub-exponential in the number of variables. Hundreds of papers in parameterized and fine-grained complexity lean on ETH to prove lower bounds; it's the kind of assumption you stack a career's worth of "conditional on ETH" theorems on top of. The new preprint describes a deterministic counting algorithm for k-CNF formulas that uses polynomial space and runs in time 2^(n/(log n)^(1/2+o(1))) multiplied by a polynomial factor. That exponent is o(n), which is exactly what ETH forbids. The algorithm is still brutally slow — nobody will ever run it on a real instance — but asymptotically it's decisive. If the proof holds, a hypothesis that structured two decades of lower-bound arguments simply stops existing.
The second claim targets the Kakeya conjecture, a geometric measure theory problem about the smallest sets containing a unit line segment pointing in every direction. The three-dimensional case fell only in 2025, in a celebrated proof by Hong Wang and Joshua Zahl that many treated as a career capstone. The announcement claims a proof in all dimensions, which would subsume that breakthrough entirely. The third result, in quantum field theory, is the vaguest of the three: described as a "unified completion of the Standard Model" but not yet released, apparently waiting on a machine-checked formalization. Physicists reading the teasers suspect something in the family of grand-unified-style constructions rather than a literal theory of everything, and the wording has earned some justified squinting.
Two things about the rollout deserve credit. The lab involved working mathematicians and physicists before going public — a direct response to the backlash that followed an earlier, clumsier math announcement, after which Terence Tao and others pushed publicly for exactly this kind of engagement. And the physics result was withheld until its formalization finished, which is the correct ordering of priorities. But hard questions remain unanswered: nobody outside knows the compute bill, whether equivalent funding directed at human researchers would have produced the same theorems, or whether a for-profit lab keeps financing curiosity-driven work once shareholders get a vote. There's also the uncomfortable loop critics flagged immediately — these models are trained partly on the questions, drafts, and forum posts of the same research community now being asked to applaud the output.
Proof-Checking vs Conjecture Generation: Two Different Jobs
Strip away the hype and every AI-for-mathematics system is doing one of two jobs. Job one is proof-checking: given a candidate argument, decide whether it's valid. Job two is conjecture generation: given a problem area, propose what's worth attempting — a lemma, a construction, an algorithm, a counterexample. They sound like two halves of a single skill. They aren't. They're different computational problems with different oracles, different failure modes, and radically different trust profiles, and conflating them is how you end up either over-trusting a press release or dismissing real progress.
Checking has an oracle. A proof written in Lean either compiles against the kernel or it doesn't, and the kernel doesn't care how confident the author sounded. Checking fails loudly — a rejected tactic block is unambiguous. Generation has no oracle. A proposed conjecture might be true, false, trivially true, or true-but-published-in-1987 under different notation. Generation fails quietly, and its failure modes are social: plausible-sounding nonsense, or genuine results dressed up as novelty. Quality here is measured by importance and originality, properties defined by human taste rather than any decidable criterion.
Why did generation suddenly get good enough to matter? Because modern reasoning models are trained for long chains of thought, not just prompted into them — reinforcement learning on verifiable rewards, mostly math and code where answers can be checked mechanically, taught these systems to actually search a space of steps rather than autocomplete one. Here's the analogy I'd keep in your head: the proof-checker is a compiler, the conjecture generator is a designer. Both are valuable. You would never, ever let the designer certify its own work.
A proof you can't check is a sermon; a conjecture you can't test is a rumor.
Where Automated Proof-Checking Wins
The checker wins wherever a formal ground truth exists and the artifact under review is too long or too tedious for a human to audit line by line. Lean 4 and its community library Mathlib have become the de facto arena here: you write definitions and proofs in a programming language, and a small, separately auditable kernel decides whether every inference step is legal. The trusted computing base is tiny compared to the mountain of mathematics built on it, which is exactly the asymmetry you want.
The practical loop looks like this: the model drafts tactic-level proof steps, the kernel accepts or rejects each one, and the rejection messages get fed back as context for the next attempt. It's the one setting where constraining model output to a strict grammar pays off immediately — you only ever sample syntactically valid tactics, so whole classes of hallucination become impossible by construction. A minimal example, the kind of lemma a model now dispatches in seconds:
import Mathlib
-- The sum of two even natural numbers is even.
theorem even_add_even {a b : ℕ} (ha : Even a) (hb : Even b) : Even (a + b) := by
rcases ha with ⟨k, rfl⟩   -- a = k + k for some k
rcases hb with ⟨l, rfl⟩   -- b = l + l for some l
exact ⟨k + l, by ring⟩    -- witness k + l; ring closes the algebra
Notice what the example demonstrates about the division of labor. The creative move is choosing the witness k + l; the checking move is ring verifying the algebra. Humans and models are both decent at the first. Only the kernel is trustworthy at the second, and it never gets tired, never skims, and never grades on vibes. The most credible element of the whole announcement is precisely this gate: the claim that the physics paper was held back until its Lean formalization completed. If that account is accurate, it's the workflow functioning exactly as intended — the machine proposes, the machine disposes, and the press release waits its turn.
Where Conjecture Generation Wins
Generation wins wherever the search space is combinatorial and evaluation is cheap. DeepMind's FunSearch established the template back in 2023: a language model proposes program-shaped hypotheses, a fast evaluator scores them, and an evolutionary loop keeps the best — a setup that produced new constructions for cap sets and better bin-packing heuristics than decades of hand-tuning. AlphaEvolve pushed the same idea further and, among other results, shaved a multiplication off a 4×4 matrix-multiplication algorithm that had stood since Strassen's era. Nobody claims these systems understand geometry. They don't need to. They need to propose, and the evaluator needs to be honest.
The ETH algorithm fits this pattern almost suspiciously well. The space of "algorithmic ideas" is enormous, and human researchers explore it with strong priors — which is a polite way of saying blind spots. A construction that requires composing a specific representation trick with a specific recursion structure can sit unexplored for thirty years simply because no one's search path ever passed nearby. Exhaustive, priors-free, slightly stupid search is precisely what machines bring to the table. The same logic powers generate-and-refute loops: propose a conjecture, immediately try to kill it with a computational search for counterexamples on small cases. Most conjectures die within minutes, which is fine — each refutation sharpens the next proposal, and the survivors are the ones worth a human's afternoon.
There's also a psychological asymmetry worth respecting. Wang and Zahl's three-dimensional Kakeya proof took years of focused effort at the very top of the field. If a model-assisted search genuinely produced an all-dimensions argument, it almost certainly found a different route through the landscape — not necessarily a deeper one, but a different one. Different is exactly what search is for. The danger isn't that machines generate conjectures; it's that someone publishes a generated conjecture without the machinery to back it. Which brings us to the part of the pipeline you actually need to build.
Building a Verification Loop for AI-Generated Proofs
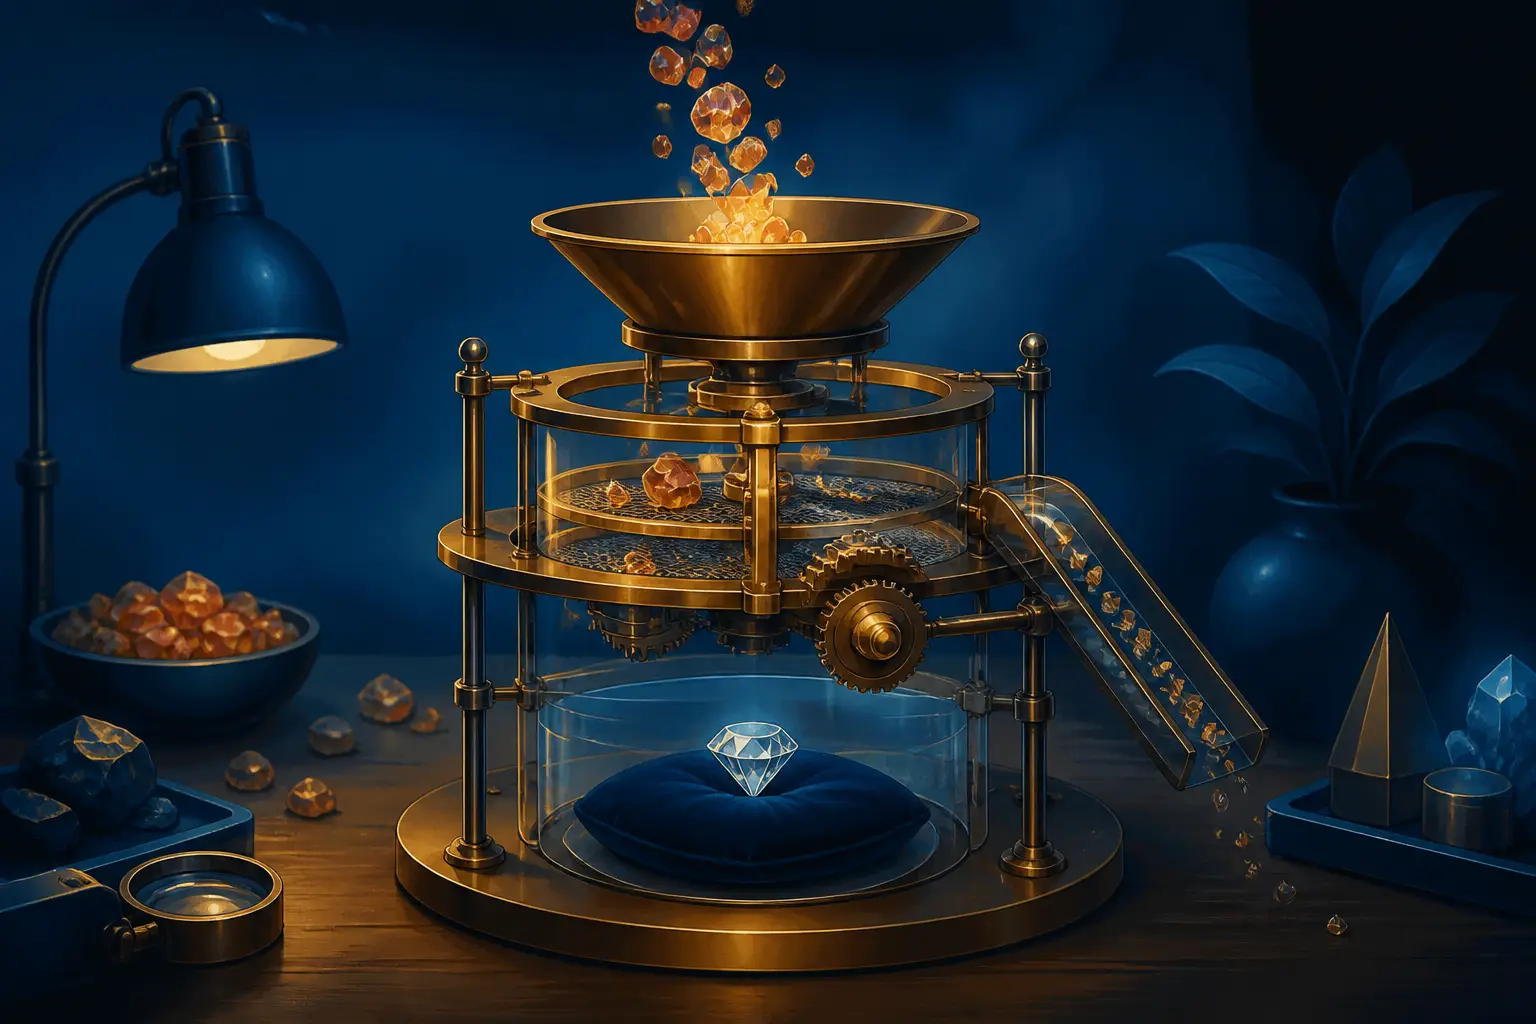
If you want the benefits of machine-generated mathematics without the embarrassment, the workflow matters more than the model. Here's the pipeline I'd run, in order:
- Generate broadly and cheaply. Diversity beats depth at this stage; you want coverage of the idea space, not one polished attempt.
- Deduplicate against the literature. Retrieval over the arXiv and MathOverflow catches the most common failure: a "new" conjecture that's a known result wearing unfamiliar notation.
- Apply cheap empirical filters. Test small cases numerically, hunt for counterexamples computationally, and let the obviously false statements die fast.
- Formalize the survivors. Lean, Isabelle, or Rocq — pick your proof assistant, but understand that this is the expensive step and a natural-language proof is a sketch, not a result.
- Human review for novelty and framing. Does this matter? Is the statement even the right one? Models optimize for what's provable; humans decide what's worth proving.
The announced collaboration roughly followed this shape — researchers were brought in before release, effectively staffing step five. That's a genuine improvement over the old drop-a-preprint-and-let-social-media-referee-it approach. But notice the asymmetry in the pipeline: steps one through three are cheap and scale with compute, step four is the bottleneck, and step five doesn't scale at all. If you're building tooling in this space, spend your money on the bottleneck — better autoformalization, better error feedback into the generator — not on a bigger, more confident generator.
Why Human Mathematicians Still Gatekeep Correctness
No verifier can tell you that a theorem matters. Problem selection is taste, and taste is a social technology built over decades — seminars, referee reports, the slow consensus about which questions open doors and which are dead ends. The research community's skepticism toward vendor announcements isn't mere gatekeeping for its own sake; it's an immune system, and immune systems occasionally overreact precisely because underreaction is fatal.
Then there's provenance. These models are trained on the community's own questions, drafts, and forum posts, which raises the uncomfortable possibility that a celebrated "discovery" is a recombination of things its future referees wrote. The fear of racing your own tool isn't paranoia — it's a data-lineage problem, and until labs can show lineage, human referees remain the only plagiarism detectors that work. Layer on the politics of credit — who gets invited to verify, whose names appear on the announcement, accusations of favoritism — and you see why the human gate isn't removable. Selecting five eminent scientists to bless a result is as much a political act as an epistemic one.
One more caution for anyone tempted to read leaderboards as research ability: competition gold medals measure performance on problems engineered to be solvable in hours. Research is the opposite distribution — problems selected because nobody knows whether they're solvable at all. It's the same reason benchmarks miss most of real work in software engineering: the metric rewards the shaped problem, not the messy one. A model that aces olympiad problems has demonstrated something real. It has not demonstrated judgment.
The Recommendation: Trust the Loop, Not the Model
Here's my position, stated plainly. Conjecture generation is real, useful, and will only get better; unverified conjecture generation is worthless, and natural-language proofs without formal backing should be treated as marketing until proven otherwise. Proof-checking wins every time the artifact must be believed. Generation wins every time the bottleneck is imagination rather than rigor. The announcements that matter are the ones where the two are bolted together.
So treat the model as a prolific junior collaborator with infinite energy and no judgment: everything it hands you goes through the proof assistant before it goes into the paper, and through a human with taste before it goes into the introduction. If you're a researcher, learn one proof assistant properly — formalization is the bottleneck, and the people who can drive it are about to be very busy. If you're building tools, build the loop, not the demo. And when the next big announcement lands, skip the press release, open the preprint, and check whether the Lean repository exists. The claims that survive are the ones that arrive already machine-checked.


