Looped Small Models: 5 Mistakes to Stop Making in Production
Looped transformers and NVFP4 quantization changed what small models can do. Five mistakes ML practitioners still make when picking a model for production.
 Sarah Chen

A team I advised last year was paying roughly $4,000 a month to route straightforward ticket-triage prompts through a frontier API. The workload was classification and short-form summarization. A small language model running on a single GPU would have handled it, but nobody on the team believed that, because the last time they'd benchmarked a sub-30B model, it flunked their reasoning-heavy tasks and they never looked again.
That blind spot is getting expensive fast. The recent release of Inkling 2 Mini — a 26.4B-parameter open-weights mixture-of-experts model that loops its middle layers three times per token — posted agentic coding scores ahead of every open model under 100B parameters, while fitting in about 20GB of memory. A model that runs offline on a laptop just out-resolved models several times its size on SWE-bench-style tasks. The gap between "small" and "capable" has narrowed to the point where most of the rules practitioners carry around about model sizing are simply stale. Here are the five mistakes I see most often, and what to do instead.
Mistake 1: Treating Parameter Count as the Capability Ceiling
The mental model most of us inherited is simple: parameters are the budget, and capability scales with the budget. That was never quite right — training data and compute matter enormously — but it was a usable heuristic until architecture started doing real work. Looping is the clearest example. Inkling 2 Mini runs its middle 12 layers (two blocks of six, out of 24 total) three times for every token, while the first and last blocks run once. The intuition: early and late layers mostly translate between embeddings and internal representations, while the middle layers carry the abstract reasoning. So you spend your compute where reasoning happens.
The published ablation is worth your attention: looping the middle 12 layers beat looping the last 12 on 27 out of 28 evaluations, and a no-loop baseline needed an estimated 1.5–1.9× more compute to match the middle-loop model's loss. That's not a marginal tuning trick. It's a different compute allocation strategy, and it breaks the naive parameter-count heuristic in a specific, predictable direction.
The fix: when you evaluate a small model, ask where the compute goes per token, not just how many weights exist. A 26B model with 3.4B active parameters and looped middle layers is doing something closer to "a small model that thinks longer" than "a small model." This connects to a point I've made before: reasoning is trained into models, not prompted out of them — and now it's increasingly architected into them too.
Mistake 2: Confusing Reasoning With Knowledge
Here's the part of the looped-model story that practitioners consistently skip, and it will bite you. Looping improves reasoning. It does not create knowledge. Facts live in weights, and weight count is what it is. The Inkling 2 Mini team is admirably blunt about this: on AA-Omniscience, a factuality benchmark, the model scores in line with other models its size. Their variable-loop research variant improved on serial-reasoning and long-context benchmarks as loops were added — out to ten loops, twice what it was trained with — but knowledge-intensive benchmarks like SimpleQA didn't budge with more passes.
I watched a friend debug this exact confusion in production. They'd swapped a bigger model for a small reasoning-forward one on a support-bot workload, saw the reasoning quality jump, and shipped. Two weeks later: hallucinated product SKUs, invented policy details. The model reasoned beautifully about facts it simply didn't contain. One early Hacker News tester hit the same wall within two prompts — asking for a WordPress plugin exercising obscure API corners produced confident, well-structured, wrong code.
The fix isn't "use a bigger model." It's architectural: pair the small reasoner with retrieval and tools. Notably, Inkling 2 Mini leads comparable open models on BrowseComp and DeepSearchQA — benchmarks that measure search and tool use. A small model with good tool hygiene often beats a big model recalling stale facts, because retrieved context is current and auditable. My rule: if your workload's failures are reasoning failures, a looped small model helps. If they're knowledge failures, fix your retrieval, not your parameter count.
Mistake 3: Dismissing Low-Bit Quantization Out of Hand
Five years ago, "we quantized it to 4-bit" was an apology. You accepted a real quality hit in exchange for fitting on smaller hardware, and anything below 4-bit was a science project. That assumption is now costing people real hardware budget. Inkling 2 Mini was trained end-to-end in NVFP4 and is deployed natively in NVFP4, with only the last four layers in MXFP8 — quantization isn't a post-hoc compression step, it's part of the training recipe. The result: a ~20GB footprint with quality comparable to BF16 peers.
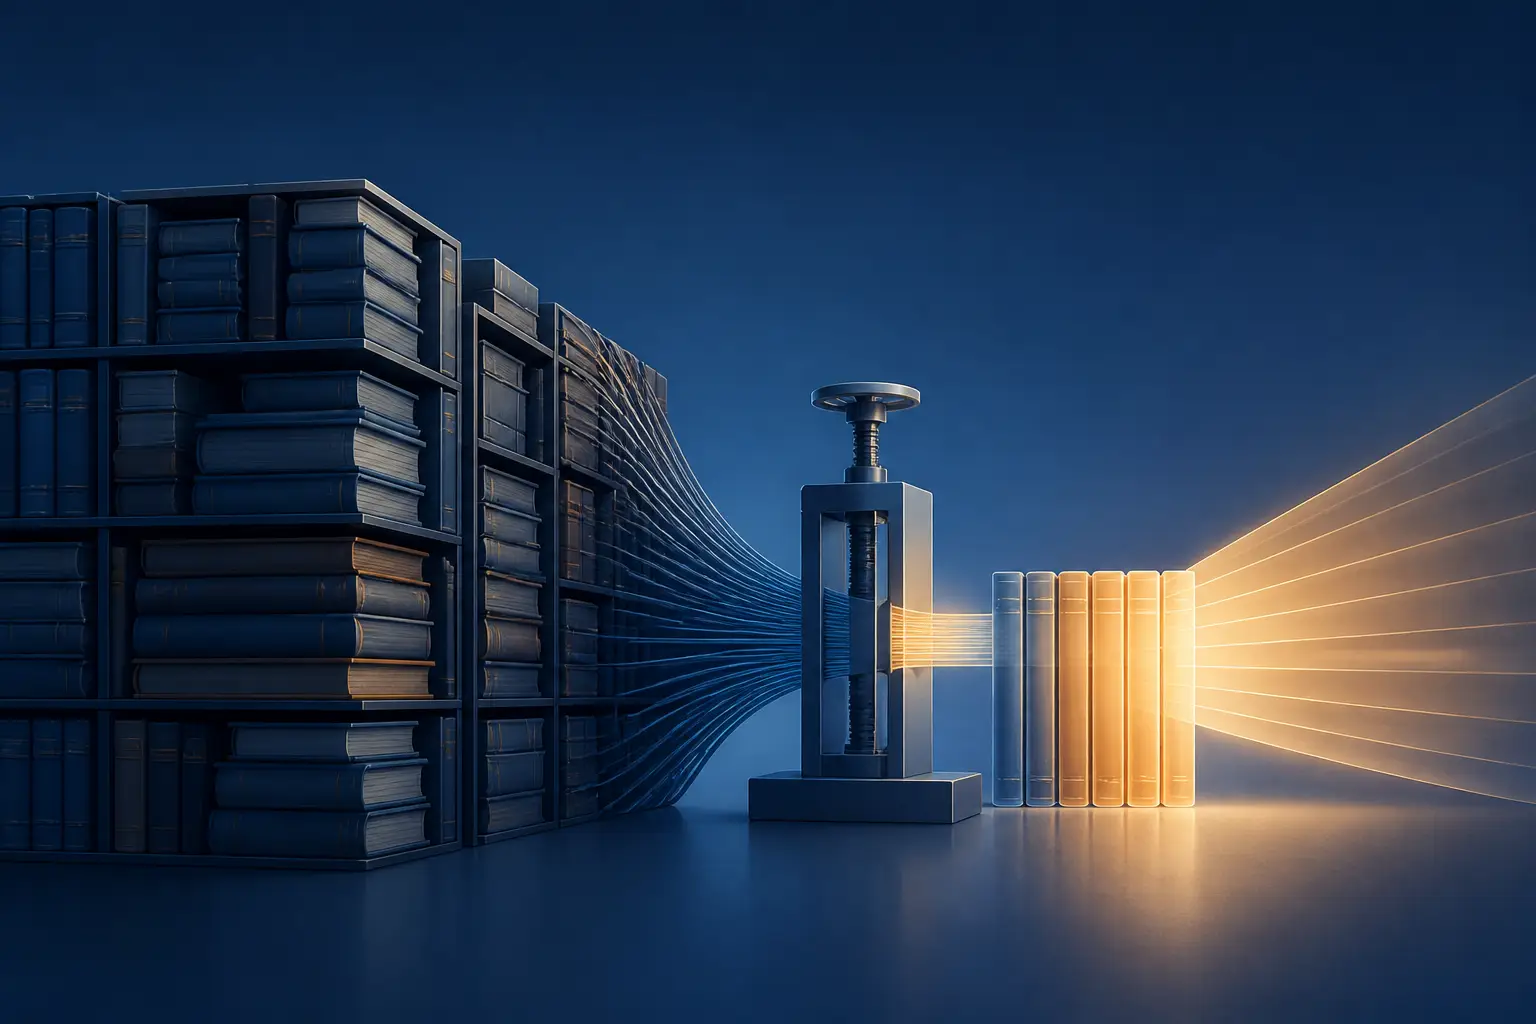
The downstream effect is striking. The Unsloth team — who know quantization pain better than anyone — observed that these natively low-bit models respond unusually well to further quantization, reportedly holding around 90% top-1 agreement even at 1-bit. There's a GGUF build on Hugging Face within days of release, and practitioners are already running it on a MacBook Pro on a plane (the team literally demoed it building a playable flight simulator offline mid-flight) and on consumer GPUs like the 7900XTX.
The fix: stop treating quantization as degradation and start asking whether a model was trained at low precision. If it was, the 4-bit (or lower) artifact is the first-class citizen, and your "we need 80GB of VRAM" sizing math needs redoing. If you're exploring what this unlocks for offline deployments, we covered the architectural patterns in building an LLM that works offline and the hardware side in running LLMs on your own hardware.
Mistake 4: Benchmarking Once and Freezing Your Model Choice
The most expensive mistake isn't technical. It's procedural. Teams run a bake-off when they first build a feature, pick a model, and treat that decision as permanent. But the capability-per-parameter frontier is moving faster than most procurement cycles. Inkling 2 Mini posted 48.2% on DeepSWE v1.1 and 46.5% on Vals Index v2.2 — leading every open-weights model under 100B total parameters — and did it while decoding faster than similarly performing models, because a MoE with 3.4B active parameters reads far fewer weights per token than a dense 27B. A model choice made nine months ago isn't a decision anymore; it's an unexamined habit.
But re-benchmarking naively is its own trap. Public leaderboards measure what benchmark authors thought was interesting, not what your product does. This is the core problem behind why AI benchmarks miss most of real work, and small models make it worse because their profile is spikier: Inkling 2 Mini is best-in-class at agentic coding yet scores a middling 50.0% on MultiChallenge and 33.4% on ComplexConstraints — behind Qwen3.8-27B on both. If your workload is constraint-heavy multi-turn chat, the headline coding numbers are irrelevant to you.
The fix: maintain a small, versioned eval suite built from your own production traffic — 200 to 500 real cases with known-good outputs — and run new model releases against it quarterly. This is cheaper than it sounds and catches both directions of surprise: models that are better than their benchmarks suggest (one commenter noted Inkling 2 Small "felt better than the benchmarks suggested") and models that ace leaderboards while failing your constraint-heavy prompts. Budget a day per quarter. It will pay for itself the first time it lets you drop a model tier.
Mistake 5: Ignoring the Cost Side of the Ledger
Model selection conversations obsess over accuracy and treat cost as an afterthought. That's backwards in production, where the cost curve determines what's even feasible. Stanford's Hazy Research Lab ran early intelligence-per-joule measurements on Inkling 2 Mini and got 0.703 — versus 0.430 for Qwen3.6-35B-A3B, 0.159 for Gemma-4-26B-A4B, and 0.036 for Qwen3.5-27B. That's not a few percent better; it's a different regime. And it compounds: a model that reaches answers in fewer tokens (looping's whole pitch is reasoning without writing the reasoning down) spends less on both compute and latency per task.
The practical consequence that excites me most is multi-agent density. Because it's a small MoE, you can fit several agents' KV caches in one GPU's VRAM — the demo of 20 simulated villagers all powered by one offline MacBook is cute, but the serious version is a dozen production agents on one DGX Spark or a single workstation instead of a fleet of API calls with per-token billing and data egress. We've written about the broader shift toward this tier in why flash-tier LLMs are the real inference efficiency story, and looped small models sharpen the argument considerably.
The fix: build your cost model around cost per completed task, not cost per token. Looping adds wall-clock time per token (those middle layers run three times, and the memory bandwidth math gets repeated reads), so naive tokens-per-second comparisons can mislead in either direction. Measure end-to-end: did the task resolve, how many tokens did it take, how much energy and latency did it burn. A model that's 20% slower per token but resolves in half the tokens with fewer retries wins every time.
What to Actually Do on Monday
- Audit your API spend by task type. Anything that's classification, extraction, routing, or short agentic loops is a candidate for a sub-30B local model. Price it out.
- Split your eval suite into reasoning failures and knowledge failures. Looped small models fix the first. Retrieval fixes the second. Don't conflate them.
- Check whether your candidate model was trained at low precision. If yes, test the 4-bit artifact first instead of last — it's the native form.
- Benchmark on your own traffic, quarterly. Public scores are a screening tool, not a decision.
- Prototype one multi-agent workload on local hardware. The economics of persistent agents change completely when there's no per-token meter.
The bigger shift here isn't any single model. It's that the frontier labs' research directions — looping, quantization-aware training, aggressive expert pruning with healing — are now landing in open weights within months, sized for hardware you already own. The practitioners who win the next few years won't be the ones with the biggest API budgets. They'll be the ones who re-examine their model assumptions on a schedule, because the assumptions have a shorter shelf life than the code does.
A small model that reasons well and retrieves honestly beats a big model that remembers confidently and reasons lazily — on cost, on latency, and often on accuracy.


