Mechanistic Interpretability Myths Put to the Test
Mechanistic interpretability was written off as untangling arbitrary knots. New evidence says networks are cleaner than we thought. We test five beliefs.
 Elena Vasquez

For years, the conventional wisdom in mechanistic interpretability was grim: neural networks are tangled knots, and before you can understand one you first have to pay a second model to untangle it for you. That belief shaped research agendas, justified entire subfields built on sparse autoencoders, and quietly convinced a lot of engineers that looking inside an LLM was a fool's errand. A researcher who helped create that pessimism just walked much of it back — and whether or not you buy the strongest version of the claim, it's a good moment to re-examine what we think we know about model internals. Let's test five common beliefs against the evidence.
Myth 1: Neurons Are Hopelessly Polysemantic
The founding legend of modern interpretability is the polysemantic neuron — a single unit that fires for cat faces and car fronts, two things with no obvious relationship. If neurons routinely bundle unrelated concepts, the reasoning went, then understanding a network neuron-by-neuron is dead on arrival. That example did enormous rhetorical work. It was the Exhibit A that justified the whole 'networks are knots' worldview.
The new claim is that Exhibit A was misread. When researchers traced the actual circuit behind the famous car-and-dog neuron, nothing downstream ever read that particular combination back out. The neuron wasn't smuggling a car feature through unrelated territory; it was doing ordinary generalization and composition. And the messiest layer of the early field's favorite model organism — the final layer of InceptionV1, once judged to contain almost no interpretable neurons — turns out to be 99–100% cleanly interpretable after ordinary architectural fixes, with no change to model size or training data. The knot was, to a large degree, a measurement artifact.
Language models show the same pattern at a different scale. Audits in 2023 gave the median neuron in a small transformer a zero on an interpretability rubric, and a large automated explainability project found roughly 1.7% of neurons legible. Preliminary audits of modern 32B-parameter models with better tooling now estimate around 90% of neuron poles have one main job, another ~7% have two related jobs, and only a few percent remain genuinely mysterious. The remaining 'polysemanticity' often dissolves on inspection: a neuron that seems to detect both a suffix and a full phrase like 'do it yourself' isn't bundling unrelated things — it grew from one to the other.
My read: the belief is dead, but its funeral should be modest. One skeptical commenter pointed out that progressive feature complexity has been known since the CNN era, and condensed, non-semantic representations are documented elsewhere. 'Less polysemantic than we feared' is well supported. 'Never polysemantic' is not proven.
Myth 2: Superposition Is a Fundamental Learning Principle
Superposition was the elegant theory that explained the mess: when a network runs out of neurons, it stops grouping similar things and starts folding unrelated things into the same unit, exploiting the geometry of high-dimensional spaces so they don't interfere. Under this theory, which concepts share a neuron tells you almost nothing — the folding is arbitrary, one of many equally good configurations. You must unfold before you can study.
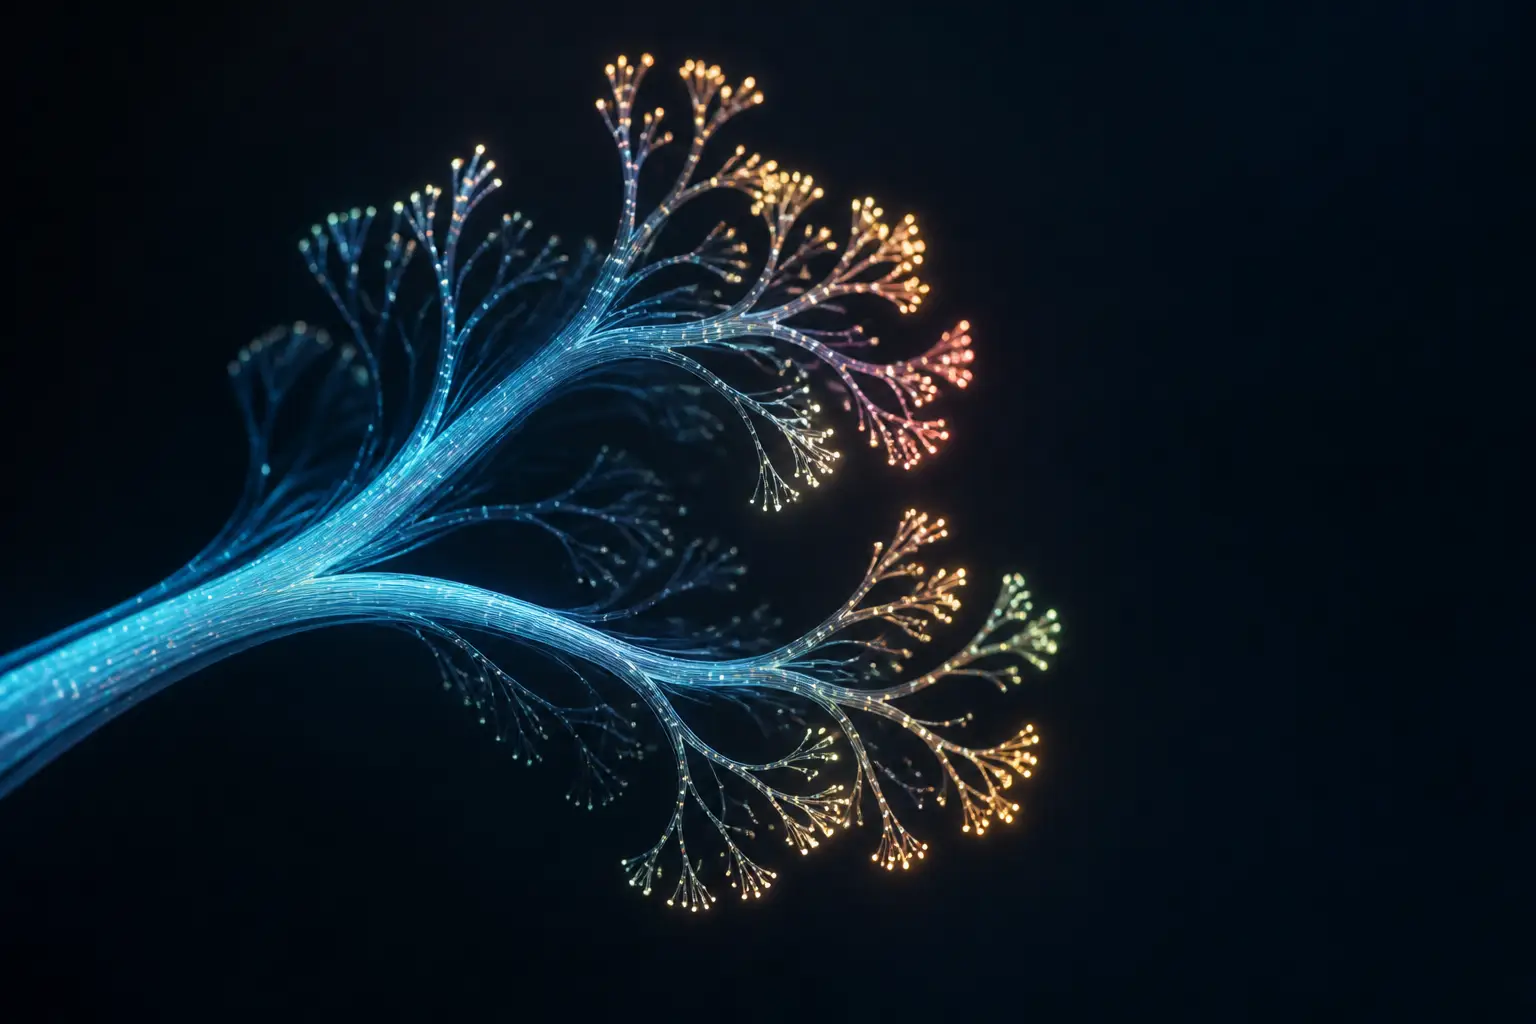
The counterproposal is almost disappointingly simple: there is only one learning principle, and it's generalization. What looked like folding is actually recursive generalization — neurons sprout offshoots the way a tree branch sprouts sub-branches. A neuron detecting 'iy' grows to detect 'diy', then the whole concept 'do it yourself'. Every expansion is into adjacent semantic territory, never into randomness. And when you shrink a model, it doesn't switch strategies: the neurons just get coarser, one 'car' neuron covering many kinds of car instead of specializing. Scale it up across a 300× size range and the same legibility holds — the neurons differentiate, they don't tangle.
This matters because it changes what a neuron's grouping means. Under superposition, a neuron firing for two things is noise. Under recursive generalization, it's a hypothesis about the model's concept hierarchy — there's something to learn from why those things share a home. It also means explanations can be fractal: start with a coarse label, zoom in when you need detail. For engineers, that's the difference between a hexdump and a stack trace with symbol names.
Two explanations were on the table: generalization groups similar things together, superposition groups unrelated things together. The field bet on the wrong one.
I'd add one caveat the enthusiasts gloss over: superposition as a mathematical phenomenon — features represented in fewer dimensions than there are features — is well established in toy models. What's disputed is whether it's the right explanation for the canonical messy neurons in real networks. Those are different claims, and conflating them is how you end up over-crediting or over-dismissing the result.
Myth 3: You Need a Sparse Autoencoder to See Anything
The practical consequence of the knot theory was methodological: don't study the network, study a decomposition of it. Train a sparse autoencoder to approximate the network 'unfolded,' then interpret the SAE's learned features instead of the original neurons. This spawned an entire pipeline industry — dictionary learning, reconstruction objectives, feature dashboards — and some genuinely impressive results, like Anthropic's monosemantic features extracted from Claude-scale models.
But notice what the SAE approach assumes: that the original network is illegible and the approximation is where the truth lives. If networks are already clean, that assumption inverts. The network's own neurons and circuits become the primary object of study, and the SAE becomes at best a compression tool — useful for summarizing, dangerous if you mistake the summary for the system. SAEs have their own failure modes: they can invent features that reconstruct activations well without corresponding to any real mechanism, and their reconstruction errors are exactly the kind of thing that bites you in safety-critical analysis.
The alternative workflow looks more like ordinary debugging. Pick a neuron. Look at its strongest activations, then its weak ones (weak activations turn out to be informative — the famous 'Titanic neuron' weakly fires for era-adjacent things like steam engines, which is generalization, not confusion). Trace what it connects to downstream. In mixture-of-experts models, check what its expert specializes in. Understanding compounds like a crossword: each neuron you decode constrains the ones around it. None of this requires training a second model.
- Start from strong activations of a single neuron, then inspect weak activations for the generalization boundary.
- Follow connections downstream to see what actually reads the neuron's output — many 'mysteries' die here.
- Use the surrounding circuit and expert specialization as cross-checks, the way you'd use callers and callees in a profiler.
- Reach for SAEs when you need compression or search, not as the ground truth about mechanism.
Myth 4: Small Models Tell You How Big Ones Work
Most of the pessimistic canonical results came from small or simplified models — one-layer transformers, early vision networks. There's a convenient irony here: small models really do run out of room, which made superposition the natural explanation for their behavior. But a network short on room doesn't change learning principles; its neurons just get broader. Broad neurons look like arbitrary mixtures to primitive tools. Scale the model up, and those broad neurons differentiate into clean, specific ones.
The same logic applies to tools. The 2023-era automated explainers couldn't run the loop of conjecture and test — they generated a hypothesis from activations and scored it by simulation, which rewards plausible-sounding explanations over correct ones. Modern agentic tooling can actually intervene: patch activations, ablate a neuron, predict the effect, check the result. That closed loop is what turned '1.7% interpretable' into '~90% one main job' more than any property of the models themselves. We should be humble about how much of the literature measures our instruments rather than the networks.
There's a parallel here to other cases where the gap between a spec and a running system hid the real behavior — the specification-implementation gap is where bugs live, and it's also where interpretability phantom bugs lived. The model's weights were the ground truth all along; our descriptions of them were the buggy spec.
Myth 5: Interpretability Doesn't Change How You Build
Even practitioners who followed the interpretability literature often filed it under 'safety research, relevance: someday.' That's wrong now, whatever you think of the strongest claims. If neurons and circuits are legible building blocks, they become handles: steerable features you can clamp, amplify, or ablate at inference time. Feature steering — boosting a 'truthfulness' direction, suppressing a 'sycophancy' direction — is already a working technique, and it's strictly more principled when the feature corresponds to a real mechanism rather than an SAE's reconstruction artifact.
For debugging, the payoff is anticipation. When a model misbehaves on a class of inputs, the current practice is prompt archaeology and vibes. A legible circuit gives you something closer to a profiler: which features fired, what read them, where the decision actually happened. This complements rather than replaces behavioral techniques — if you're shaping model outputs for production, constrained decoding handles the output contract while interpretability handles the why. And for agents acting autonomously, internal observability adds a dimension that external guardrails can't: we've argued before about containment versus monitoring for AI agents, and monitoring gets substantially stronger when you can watch mechanism, not just behavior.
One more implication deserves emphasis, and it's about access. This entire research program depends on open weights. You cannot audit circuits in a model you can only query through an API. If understanding internals is a prerequisite for trusting increasingly autonomous systems — and I think it is — then weight openness isn't a nice-to-have ideology, it's the foundation of the whole debugging story.
What to Actually Take From This
Strip the hype away and the defensible core is this: the canonical evidence that networks are arbitrarily tangled has not held up under re-examination, modern models with modern tools look dramatically more legible than the 2023 literature suggested, and the remaining mess has structure — fractal generalization — that you can exploit rather than untangle. The strong version, 'interpretability is basically solved, just scale it,' has a familiar hypomanic ring to anyone who watched the first wave of SAE enthusiasm, and it deserves the skepticism it's getting.
For working engineers, my advice is concrete: stop treating model internals as a black box by default. The tooling for probing activations, steering features, and tracing circuits is maturing fast, and the conceptual barrier — 'it's all arbitrary knots anyway' — was never as load-bearing as it seemed. Neural networks may not be clean in the way our code is clean. But they're a lot closer to legible systems than to magic, and legible systems are things we know how to engineer with.